2026 Dev Decision: LlamaIndex vs LangChain and When to Add LangGraph
Developer first 2026 comparison of LlamaIndex and LangChain. Learn when to start with retrieval, add LangGraph agents, or move to a production...
Pick LlamaIndex when your problem is retrieval over documents. Pick LangChain, run on the LangGraph runtime, when your problem is a multi-step agent that calls tools, holds state, and needs to survive a crash mid-task. Most production systems we've seen end up running both, with LlamaIndex handling ingestion and query while LangGraph handles the loop. Section 6 below walks through that hybrid pattern in detail.
TL;DR:
- LlamaIndex excels at document ingestion and retrieval, offering default hybrid search and layout-aware parsing for complex enterprise formats.
- LangChain and LangGraph focus on orchestrating multi-step, durable agents that can handle retries, human approval, and state persistence, suitable for complex workflows.
- Combining both frameworks is common in production, with LlamaIndex providing accurate document retrieval and LangGraph managing the agent's multi-step logic and failure recovery.
- Integration considerations include support for popular models, vector stores, document loaders, and observability tools, which should align with existing infrastructure before development.
- When scaling beyond prototypes, adopting an orchestration operating system like agent-swarm offers durable memory, seamless tool integrations, and simplified multi-project management.
Table of Contents
- LlamaIndex vs LangChain: Where the Complexity Actually Lives
- What LlamaIndex Gets Right: Ingestion, Indexes, and Retrieval
- LangChain and LangGraph: Built for Agents That Need to Survive Failure
- Integration Landscape: Models, Vector Stores, and Observability
- The Hybrid Pattern: LlamaIndex Retrieval Inside a LangGraph Agent
- How to Choose: A Decision Checklist for Engineers
- Running It in Production: Parsing, Memory, and Cost Control
- When a Production Orchestration OS Beats a Framework
- Run Your Agents on agent-swarm Instead of Gluing Frameworks Together
- Sources
- FAQ
LlamaIndex vs LangChain: Where the Complexity Actually Lives
The two frameworks solve different halves of the same problem, and that split shows up in their architecture, not just their marketing copy.
LlamaIndex's center of gravity is the index. Everything revolves around getting unstructured data into a shape a language model can query well: documents get parsed, chunked, embedded, and organized into one of several index structures, then pulled back out through a query engine tuned for relevance. The framework's job is to make retrieval accurate with minimal manual tuning.
LangChain's center of gravity is the agent loop. LangChain recommends its LangGraph runtime for anything that needs durable, multi-step execution: an agent that decides which tool to call, waits on a human approval, retries after a failure, or picks up exactly where it left off after a container restart. The framework's job is to make orchestration reliable, not to make retrieval better.
That split changes where your bugs come from and who owns them:
- In a LlamaIndex-heavy system, most debugging time goes into retrieval quality: wrong chunks retrieved, stale embeddings, or a query engine returning irrelevant nodes. This work looks a lot like data engineering.
- In a LangChain/LangGraph-heavy system, debugging time goes into orchestration state: a checkpoint that didn't save, a tool call that returned malformed output, or an agent stuck in a retry loop. This work looks like distributed systems engineering.
- Team structure follows naturally. Retrieval-heavy projects lean on people who understand data pipelines and embeddings. Agent-heavy projects lean on people who understand state machines and failure recovery.
By 2025 and into 2026, both projects moved toward the middle. Independent analysis of the two frameworks notes that LangChain rearchitected heavily around agents and LangGraph, while LlamaIndex expanded into workflow orchestration and much richer document parsing. Older reviews that describe one as "just RAG" and the other as "just agents" are describing frameworks that no longer exist in that simple form.
What LlamaIndex Gets Right: Ingestion, Indexes, and Retrieval
If your workload is document-heavy, LlamaIndex saves you weeks of assembly work. LlamaIndex ships opinionated retrieval defaults that most teams would otherwise have to build by hand: hybrid search combining keyword and vector methods, reranking models, and chunking strategies tuned for different document types.
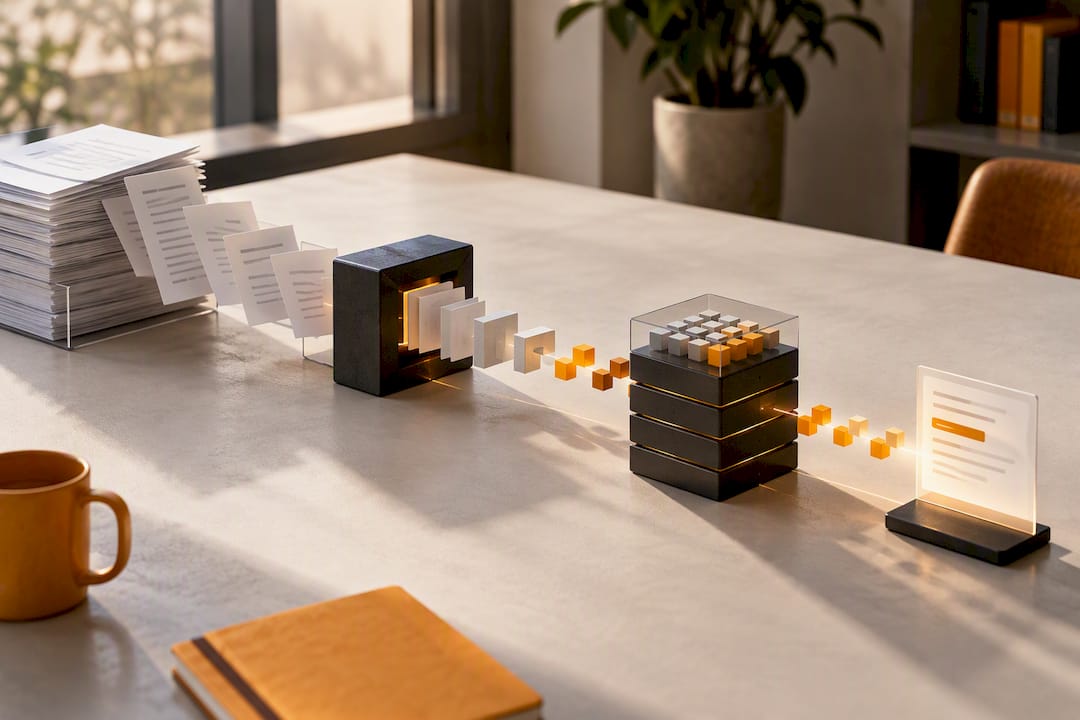
The parsing layer deserves specific mention. LlamaParse, LlamaIndex's commercial parsing component, handles the messy reality of enterprise documents better than most open-source alternatives. Layout-aware parsing means it preserves table structure, extracts values from charts, and reads scanned PDFs without turning a two-column financial report into scrambled text. LlamaParse and the LlamaCloud managed service extend this to over 130 supported file formats, which matters the moment your ingestion pipeline hits a PowerPoint deck or a spreadsheet with merged cells instead of a clean text file.
LlamaIndex's index types map to specific retrieval problems rather than forcing one generic pattern:
- Vector index: standard semantic search over embedded chunks, the default for most Q&A over documents.
- Summary index: builds a summary tree over your corpus, useful when queries need broad synthesis rather than a single passage.
- Tree index: hierarchical structure good for documents with clear parent-child relationships, like nested legal clauses.
- Property/graph index: models entities and relationships explicitly, useful when questions depend on connections between facts rather than passage similarity alone.
On top of these, retrieval primitives like recursive retrieval (querying a summary first, then drilling into the source chunk) and reranking (re-scoring an initial candidate set with a smaller, sharper model) push accuracy up without touching your prompt.
Pro Tip: Start with the vector index and hybrid search before reaching for anything more exotic. Most retrieval-quality problems get solved by better chunking and reranking, not by a fancier index type.
The ergonomic payoff is real: a working RAG prototype in LlamaIndex often takes a fraction of the code a hand-rolled stack requires, because the defaults are already tuned for common document patterns.
LangChain and LangGraph: Built for Agents That Need to Survive Failure
LangChain's value shows up once your system stops being a single question-and-answer loop and becomes something that has to plan, act, wait, and recover. That's where the LangGraph runtime does the real work.
LangGraph's core primitives are built around durability, not just chaining prompts together:
- Checkpointers save the full state of a running agent at each step, so a crashed container or a deployment restart doesn't lose progress.
- State persistence lets an agent resume a multi-hour task exactly where it stopped, rather than starting over.
- Human-in-the-loop gates pause execution for approval before a risky action, then resume once a person signs off.
- Time-travel debugging lets you rewind an agent's execution history to inspect exactly what it decided at each step and why.
On top of that runtime, LangChain's higher-level primitives (agents, chains, tools, and memory objects) compose into workflows that call APIs, query databases, and hand off between specialized sub-agents. A support-ticket triage agent, for instance, might use one chain to classify intent, hand off to a tool that queries a CRM, and pause for human review before closing a ticket, all inside one durable graph.
Pro Tip: If your agent needs to pause for a human approval step, build on LangGraph's checkpointer from day one. Retrofitting durable state onto a stateless agent loop later is far more painful than starting with it.
The tradeoff is assembly time. LangGraph gives teams more control and a stronger observability story through LangSmith, which traces every step of an agent's run, and LangServe, which turns a graph into a deployable API. But you're wiring more pieces together yourself compared to LlamaIndex's retrieval defaults. For teams that have hit the limits of a simple orchestration loop and need real durability guarantees, it's worth reading about when a homegrown orchestrator starts breaking down before committing to a full LangGraph build.
Integration Landscape: Models, Vector Stores, and Observability
Before committing to either framework, check three integration surfaces against your actual stack, because gaps here turn into weeks of glue code later.
- Model providers and vector stores. Both frameworks support the major players: OpenAI, Anthropic, and the usual local-model runtimes on the model side; Qdrant, pgvector, Chroma, and Pinecone on the vector store side. Neither has an exclusivity advantage here, so this rarely decides the choice.
- Document loaders and connectors. LlamaIndex's loader ecosystem leans toward document-heavy sources: Google Drive, Notion, SQL databases, and audio transcription connectors are well covered. LangChain's ecosystem is broader in raw count, with over 1,000 community-maintained wrappers across vector databases and model providers, which shortens onboarding when you need to support many vendors at once rather than one deep pipeline.
- Observability and evaluation. LangSmith gives LangChain and LangGraph users detailed run tracing, evaluation datasets, and prompt versioning built for agent debugging. LlamaIndex's observability leans more on community integrations and third-party tracing tools rather than one unified native platform.
None of these gaps are disqualifying on their own. The point is to check them against your existing infrastructure before you write the first line of orchestration code, since swapping a vector store mid-project costs far more than picking correctly up front.
The Hybrid Pattern: LlamaIndex Retrieval Inside a LangGraph Agent
The most common production architecture we see isn't LlamaIndex or LangChain. It's both, wired together with LlamaIndex handling data and LangGraph handling decisions.
The flow works in three steps:
- A LangGraph agent receives a user query and decides, as part of its planning step, that it needs information from your document corpus.
- The agent calls a tool that wraps a LlamaIndex query engine, which is doing hybrid search, reranking, and recursive retrieval behind the scenes on your indexed documents.
- The query engine returns relevant passages to the agent, which incorporates them into its next reasoning step, possibly calling more tools, before producing a final answer.
This pattern lets each framework do what it does best: LlamaIndex's retrieval defaults get you accurate document answers with less tuning, while LangGraph's checkpointer keeps the overall task durable across retries and multi-step plans.
The cost is added surface area. Every hop between the agent and the query engine adds latency, and you now have two systems to monitor instead of one. Token cost also compounds: the agent's planning step consumes tokens deciding to call the retrieval tool, then the retrieved passages consume more tokens once they're stuffed back into the agent's context. For a single Q&A endpoint, that overhead isn't worth paying. For a multi-step agent that occasionally needs document lookups, it's the standard shape.
How to Choose: A Decision Checklist for Engineers
Run through this before you write a single line of framework code.
Step 1: Name the workload. Write down your acceptance criteria in one sentence. "Answer questions about our PDF corpus with 90%+ relevant citations" points to LlamaIndex. "Complete a multi-step approval workflow that survives restarts" points to LangGraph.
Step 2: Check the nonfunctional requirements.
- Does this need to persist state across hours or days? That favors LangGraph's checkpointers.
- Does this need audit trails for compliance? LangSmith's tracing is built for that.
- Are your documents scanned, tabular, or otherwise messy? That favors LlamaParse.
- What's your team's existing skill set: data pipelines, or distributed state machines?
Step 3: Pick a starter stack.
| Workload | Starter stack |
|---|---|
| Quick prototype, no retrieval | Direct model API call, no framework |
| Document Q&A over a corpus | LlamaIndex with default vector index |
| Multi-step tool-using agent | LangChain's create_agent on LangGraph |
| Both, at production scale | LlamaIndex retrievers as LangGraph tools |
Independent benchmarking suggests answer accuracy converges once both frameworks are assembled from comparable components, so don't over-index on marginal accuracy claims. Migrate to the other framework, or add it as a layer, once your document complexity outgrows a simple index or your agent's tool use outgrows a single loop.
Running It in Production: Parsing, Memory, and Cost Control
A few implementation decisions determine whether your system stays cheap and debuggable once it's live.
Pay for LlamaParse when your documents are scanned, contain tables, or mix layouts unpredictably; build custom ETL only when your source format is clean and consistent, since custom parsing code degrades fast against real-world document variety.
- Use session summaries or time-weighted retrieval instead of dumping full conversation history into every prompt; raw logs bloat token cost fast.
- Favor reranking over larger context windows when retrieval precision is the bottleneck. A smaller context with a good reranker usually beats stuffing more chunks into the prompt.
- Pick your embedding model deliberately. Swapping it later means re-embedding your entire corpus.
- Log every agent step with checkpointer state attached, so a failure can be replayed instead of guessed at.
Pro Tip: Track token cost per query type, not just per request. A retrieval-heavy query and a pure-reasoning query have wildly different cost profiles, and averaging them hides where your budget is actually going. For a deeper look at context window discipline, see managing context windows in production.
When a Production Orchestration OS Beats a Framework
Frameworks solve the code layer. They don't solve what happens after: who runs the containers, who owns the memory across projects, who wires up Slack and GitHub and Linear without another six weeks of glue code.
Teams tend to hit this wall once they have more than one agent workflow running and start duplicating orchestration logic across projects. That's usually the signal to stop building framework glue by hand and adopt an orchestration layer that already handles durable execution, integrations, and shared memory out of the box.
That doesn't make the framework choice irrelevant. A lightweight LlamaIndex or LangChain setup is still the right call for a single prototype or a narrow internal tool. The tradeoff shows up in customization: an orchestration OS gives you less bespoke control over the agent loop itself, in exchange for not maintaining that loop yourself.
Run Your Agents on agent-swarm Instead of Gluing Frameworks Together
Once your LlamaIndex retrieval layer and LangGraph orchestration logic both need to survive restarts, share memory across projects, and post updates to Slack without a human babysitting the process, you've outgrown a framework and need a production operating system. agent-swarm is an open-source AI work OS: a lead agent breaks down objectives, assigns tasks to specialized workers inside isolated containers, and maintains memory and context across runs instead of resetting it each time.
Three things engineering teams get immediately: durable task state that survives container restarts, integrations with popular tools already built in, and persistent memory that carries forward even if the underlying model changes. You can self-host it for free under MIT, run the Cloud plan at €30 to €100 per month, or talk to us about Enterprise support. Check the pricing page or browse real orchestration sessions to see what a production run actually looks like before you decide.
Sources
Check the LangChain vs LlamaIndex comparison for orchestration-versus-retrieval framing straight from LangChain, IBM's breakdown for a vendor-neutral conceptual overview, and DataCamp's technical comparison for feature-by-feature detail. Use official docs for API specifics and these for framing decisions.
- LangChain vs LlamaIndex: from retrieval to reliable AI agents
- LangChain vs LlamaIndex | DataCamp
- LlamaIndex vs LangChain: Which RAG Framework to Build On | Forage
FAQ
Is LlamaIndex Made by Meta?
No. LlamaIndex is an independent open-source project originally released under the name GPT Index, unrelated to Meta's Llama models despite the naming similarity. It focuses on data ingestion, indexing, and retrieval as its core strengths.
Who Are LlamaIndex's Competitors?
LangChain is the most direct competitor, alongside frameworks like Haystack that also target retrieval-augmented generation pipelines. The frameworks increasingly overlap rather than compete cleanly, since both LangChain and LlamaIndex expanded into each other's territory by 2025 and 2026.
What Is LlamaIndex Used For?
LlamaIndex is used to build retrieval systems over documents: ingesting PDFs, spreadsheets, and databases, indexing them for fast semantic search, and serving relevant passages to a language model. It's the common choice for document Q&A, knowledge base search, and enterprise RAG applications.
Is LlamaIndex Completely Free?
The core LlamaIndex framework is open source and free to use. Commercial add-ons like LlamaParse and the LlamaCloud managed service carry separate pricing for hosted parsing and scaling, which is worth budgeting for if you're processing scanned or complex documents at volume.
Should I Use LlamaIndex or LangChain for a New Agent Project?
Start with LlamaIndex if the core job is answering questions from documents, and start with LangChain's create_agent on LangGraph if the core job is a multi-step agent calling tools. If you need both, agent-swarm's orchestration layer can run either framework's retrieval or agent logic inside a durable, memory-persistent workflow instead of you wiring the checkpointing yourself.
Recommended
Related field notes
Match the Tool to Failure: LangChain Alternatives for Engineers
Choose the right LangChain alternative by failure mode, data path, control flow, or role based, and see when agent-swarm.dev fits.
Pruebas unitarias con IA: guía práctica para desarrolladores
Usa pruebas unitarias generadas por IA para crear aserciones, dobles de prueba y datos sintéticos, acelerar cobertura en semanas y evitar pruebas vacías.
Decide Fast: Which Make Alternatives Fit Your Core Constraint
Match why you are leaving Make, whether cost, data control, AI reasoning, or governance, to the right replacement with checklist and a handpicked shortlist.